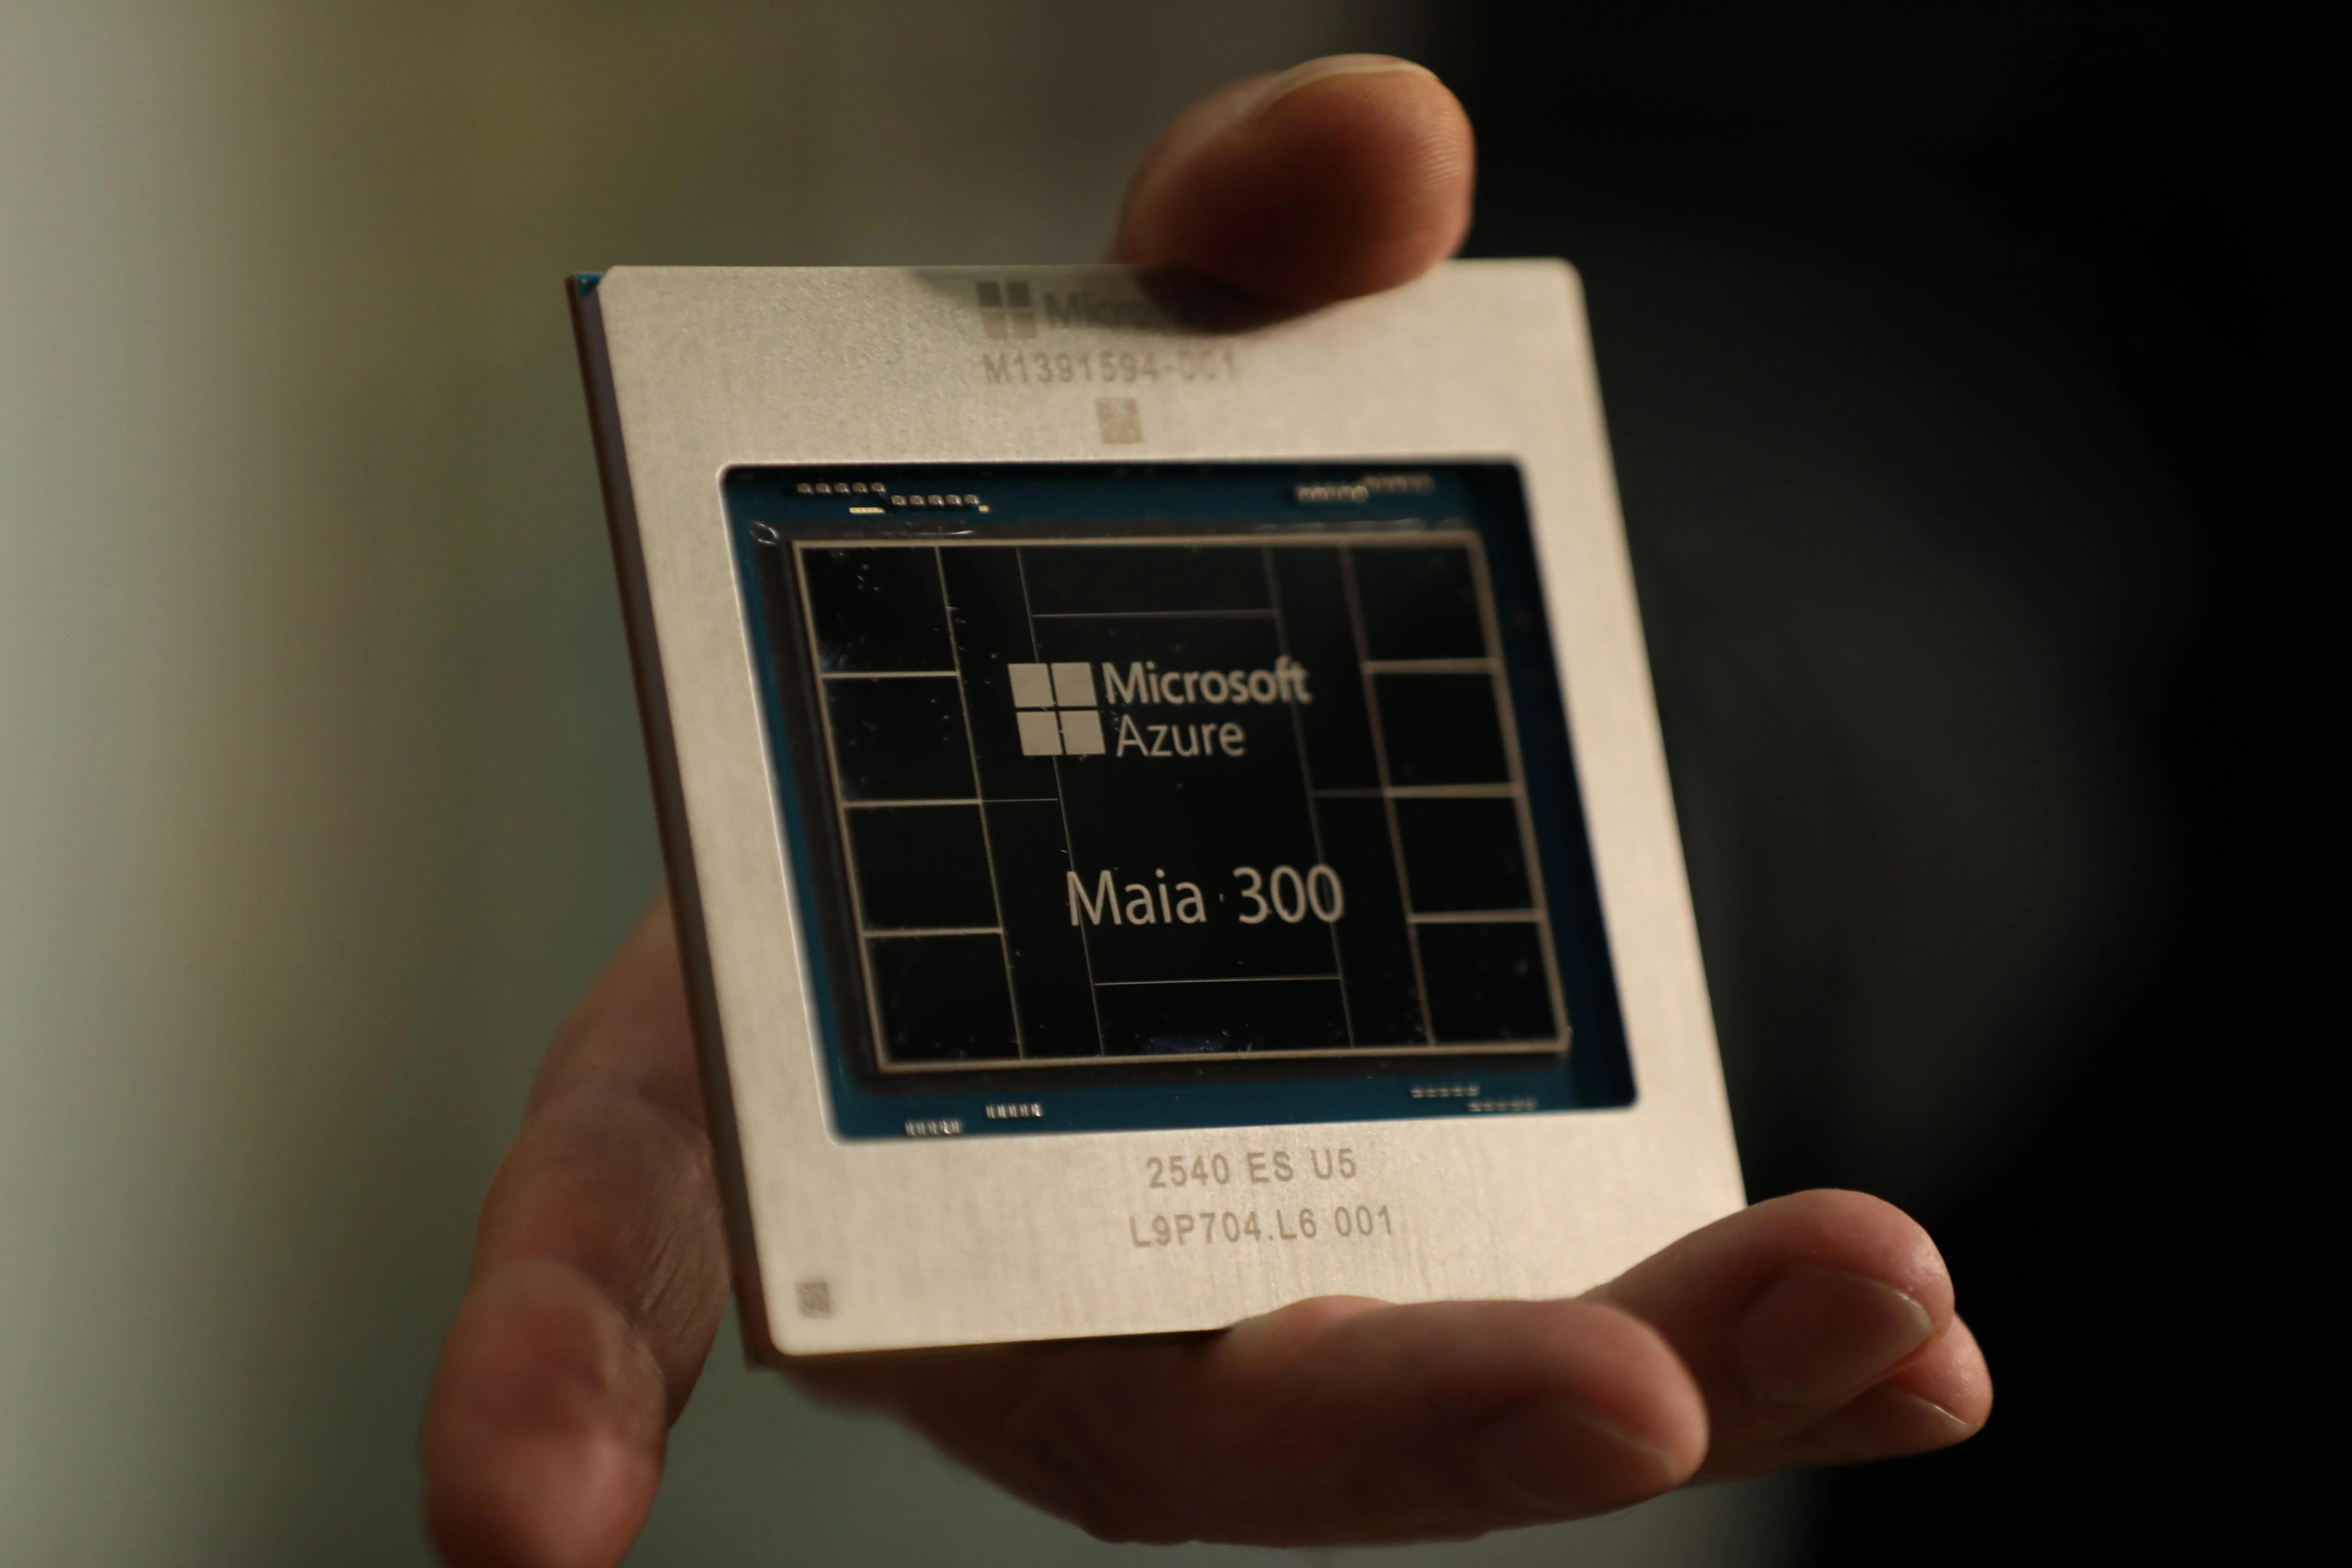
Microsoft announced Maia 300 on Monday, positioning its custom silicon as a major future engine for Copilot, GitHub Copilot and related inference services. The company claims 40 percent more tokens per megawatt than leading GPU systems and plans larger deployments beginning in 2027.
This is not a chip to order for a Mac mini. It is a signal about the economics of AI services: inference providers are trying to control hardware, electricity use and cost per useful response rather than renting every computation from a GPU supplier.
Action: when evaluating AI APIs for a paid product, keep watching actual price-per-task and reliability. Hardware efficiency claims matter only when savings and latency improvements reach customers.